Old Fucking Punk @lwriemen@librem.one
#ShlaerMellor, #FunctionPointAnalysis, #punk, #environmentalist, #unionAdvocate, #anarchosocialist #freeSoftwareAdvocate #cooperativeLife #noLLMs
"with a big old lie and a flag and a pie and a mom and a bible most folks are just liable to buy any line, any place, any time" - Frank Zappa
Joined May 2019
Old Fucking Punk
boosted

Big Tech, connecting us all. Cartoon for Dutch newspaper Trouw.
Old Fucking Punk
boosted

Yesterday I presented about the ethics of GenAI at an online conference. At the end there was a panel discussion with speakers; the moderator started with a question about panellists‘ view on GenAI. Most said something like „I strongly share Johannes‘ concerns about climate effects & destruction of society“. Then they continued with how they will use and propagate GenAI to improve results and outcomes in their special space. I left the panel prematurely. All I could have done is be a kill-joy.
Old Fucking Punk
boosted
@david_chisnall yes, so they are being consistent:
https://www.eff.org/document/amicus-brief-eff-et-al-thomson-reuters-v-ross-intelligence
Regarding Ross, specifically, there is also precedent that mere "sweat of the brow" collection of facts like phone numbers in the Yellow Pages is not copyrightable in the US, only "expressive content" like commentary would be:
https://en.wikipedia.org/wiki/Feist_Publications,_Inc._v._Rural_Telephone_Service_Co.
and in fact that is cited by the EFF brief.
In any case the paywalling of law in the US, e.g. PACER, is a scandal:
https://www.open-public-records.com/articles/pacer-paywall
You are supposed to abide by laws (or jurisprudence, which in Common Law is the same thing), and can only access them by paying.
Old Fucking Punk
boosted

To add a bit more (sorry for the double reply):
The EFF brief did not try to capture any of this nuance. It could have proposed tests for where on that spectrum you are. It could have argued that the interpolation between different works is a transformative step (though there is case law that says this is not the case if you don’t call the interpolation ‘AI’) if done with a sufficiently large data set. It could have made arguments about the size of the models versus the size of the input (note: the weights of ChatGPT are larger than a losslessly compressed copy of Wikipedia and Project Gutenberg, and compression ratios generally improve the more data you have).
It didn’t do any of these things and instead made specious arguments about ‘AI’ being special and magic and totally different from almost identical applications of exactly the same technology.
Old Fucking Punk
boosted
I am not a lawyer. I have studied IP law in various firms guided by solicitors, barristers, and professors of law of my acquaintance since I was a teenager (including reading through big piles of case histories and commentaries) but not in a formal setting (mostly I learned that I would rather invent the things in the patents than draft the patents, so changed career direction). I’ve also spent a surprising amount of my career talking to copyright and patent lawyers (almost never trademark or trade-secret specialists). I have enough of a lay-person’s understanding of the topic that I was able to spot that a clause in the contract from my US publisher was unenforceable in the state that they claimed jurisdiction because it hinged on an aspect of copyright law that the USA delegates to states and which the state in question did not have relevant laws. Their lawyers subsequently confirmed and fixed this. But I a not lawyer and this is not legal advice.
I have two objections to the EFF’s position on ‘AI’ model training. One is technical, one is social.
The technical one first.
Imagine I rip a DVD and transcode it to MPEG-4 video. This is lossy recompression. The new copy is not identical to the original. It is a derived work. There was no transformative step. Specifically, losing fidelity of reproduction is not a transformative step.
Video CODECs take advantage of redundancy. Simple CODECs build predictive patterns for redundancy in a single frame (for example, is this all one colour or a gradient? Store just that fact not every pixel). More complex ones look at the previous frame and compare it to the current one and use that redundancy. Most modern ones do this in both directions. Effectively, they create a cube of voxels, where one dimension is time, and try to find redundancy in the cube.
For copyright law, this doesn’t matter. Lossy compression is not a transformative step, no matter how complex the compression.
A lot of compression schemes (rarely for video, mostly because it doesn’t make sense for video unless you have a lot) also support special cases for large quantities of redundancy across a data set. For example, if you wanted to compress English Wikipedia with ZSTD, you would use the dictionary mode. It will come up with a list of the words (or even common phrases such as ‘citation needed’) and Huffman encode them so that each page has a short encoding for referencing them. This makes each page smaller than it would be if you compressed it individually.
Compressing Wikipedia like this is not a transformative step.
Now, imagine that you create a video compression CODEC that does this. You buy a copy of every DVD or BluRay disk available and compress them together such that you have a large dictionary of all common compressed sequences. Given a prefix of a film, each film in the input set would be reproducible with some loss of quality (not necessarily the same level of quality). Similarly, if you provided an initial vector that was not something in the training set then you’d get out video that might be similar to one of the inputs, might be similar to many, or might not be obvious to a human is close to either.
This is the crux of the argument. Deep neural networks are functionally equivalent to lossy compression schemes. The inference or generation step in ‘generative AI’ is an initial vector and a random seed that decompresses the data that might be there. If nothing from the training (input) set exactly matches (or if the random seed moves away from that path) then you’ll get something new, possibly something that’s recognisable as a lossily compressed version of the input data.
Note, in particular, that a lot of compression schemes now do take advantage of neural networks. They are one of the most efficient known ways of generating a specialised lossy compression scheme over arbitrary data. The law typically doesn’t care what specific technology an action uses, only about the outcome. In this case, that doesn’t matter: exactly the same underlying technology, used in exactly the same way, covers both ‘AI’ and compression. If one is legal then so is the other because they are the same process.
The EFF’s argument hinges on the idea that this lossy compression is a transformative step. Not only is that an idea that is not supported in case or statute law, there is case law that makes it clear that lossy compression of a work is not transformative.
Their argument would be internally self consistent if it also argued that Netflix does not owe royalties on any of the third-party videos it streams (and that they can buy BluRays on Amazon, recompress them, and then stream them without paying royalties). But there is so much case and statue law that this is not the case that they didn’t make this claim.
Instead, they tried to claim that this is permitted if you call the system ‘AI’ even though it is settled law that it is not permitted if you do not call the system ‘AI’.
Second, the social aspect. Copyright law in the USA draws its legitimacy from this line in the Constitution:
To promote the Progress of Science and useful Arts, by securing for limited Times to Authors and Inventors the exclusive Right to their respective Writings and Discoveries.
So does patent law. Patent law is more of a mess because the USA was founded just before James Watt bribed various MPs to subvert the patent system, but (due to later treaties) the modern US patent system inherits from that subversion (Watt, like Edison, was a bit of a dick).
This intent goes back to the invention of the printing press, where publishers made copies of books in large quantities without paying authors. This removed the incentive to write books. Allowing authors to control distribution rights put that incentive back. This short paragraph covers about a hundred years of the evolution of legal thought in this space, please forgive the many oversimplifications.
The EFF brief references this motivation but twists it. OpenAI and Anthropic are the equivalents of the post-Gutenberg printers. They are taking the work of creative individuals and producing output that competes directly with the products of those authors. This is precisely the situation that copyright law in the USA exists to prevent.
Yet the brief twists this to say that a lossily compressed duplication of original work is actually the kind of creativity that this was intended to cover.
This hinges on the idea that writing news, or other creative works, is a trivial commodity, whereas mechanically compressing them into a system that can lossily reproduce them is a key contribution to society.
Even if I agreed with their other arguments (I do not, I believe that they either misunderstand or deliberately misrepresent the technology and the relationship to other settled law), this is such a profoundly anti-human viewpoint. The idea that human creativity exists to feed poor-quality technological reproductions of that creativity is incompatible with any possible society that I would want to live in and I would struggle to find common ground with people who aim to create such a world.
Old Fucking Punk
boosted

the Ellison mafia turned CBSNews into a 24/7 JD4POTUS booster p̶l̶a̶t̶f̶o̶r̶m̶ couch for Vance. let’s welcome their new bootlicking loser: Rahm Emmanuel.
https://www.cbsnews.com/video/rahm-emanuel-on-possibly-running-for-president-in-2028/
Old Fucking Punk
boosted

A mental health campaign that began in Sangaria, Rajasthan, India, with a US$10,000 Humphrey Alumni Impact Award has now spread to 11 districts. Its greatest strength is not government or external funding, but the rural communities that have made it their own work and a shared responsibility.
Old Fucking Punk
boosted

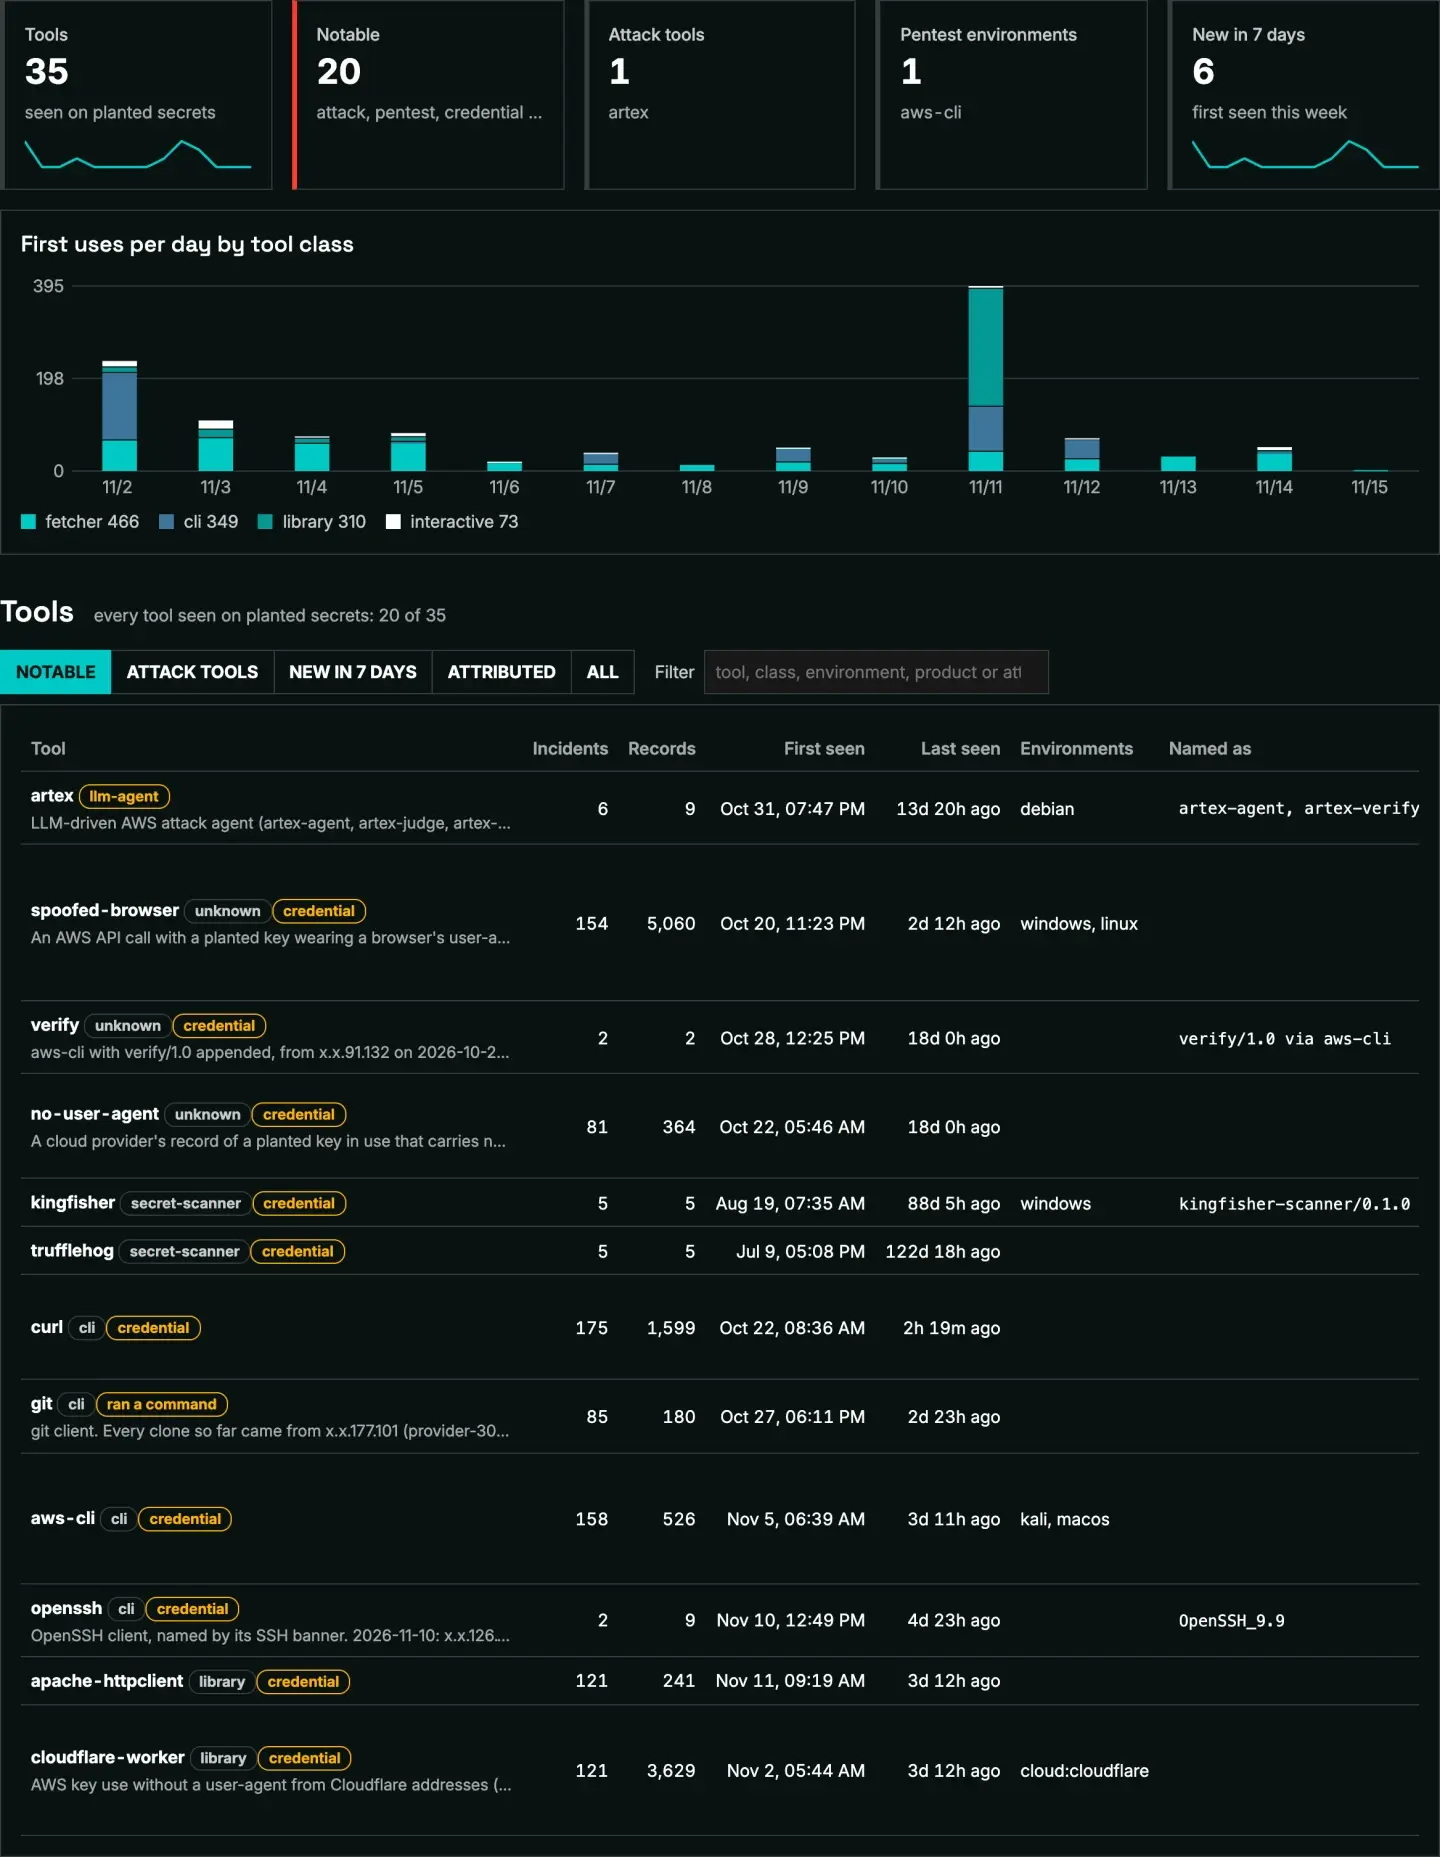
People have speculated for a while on which LLM providers might be snarfing up private data, but somehow I never had the idea of just throwing a bunch of canary tokens into prompts and seeing who bit.
These folks did, though: https://www.dragos.com/blog/ai-supply-chain-security-canary-tokens The results will surprise none of you. :-)
Old Fucking Punk
boosted

Religious messages that US Agriculture Secretary Brooke Rollins emailed to the agency's 100,000 employees were unconstitutional, according to a ruling today issued by a federal judge. https://storage.courtlistener.com/recap/gov.uscourts.cand.469951/gov.uscourts.cand.469951.59.0.pdf
Old Fucking Punk
boosted

Why does CVS pharmacy hate those with vision and cognitive disabilities? Fuck your stupid screens at the pharmacy counter.
Old Fucking Punk
boosted
From Hospitals to Palantir HQ: Protests Across England Over Controversial Healthcare Data Deal
Old Fucking Punk
boosted
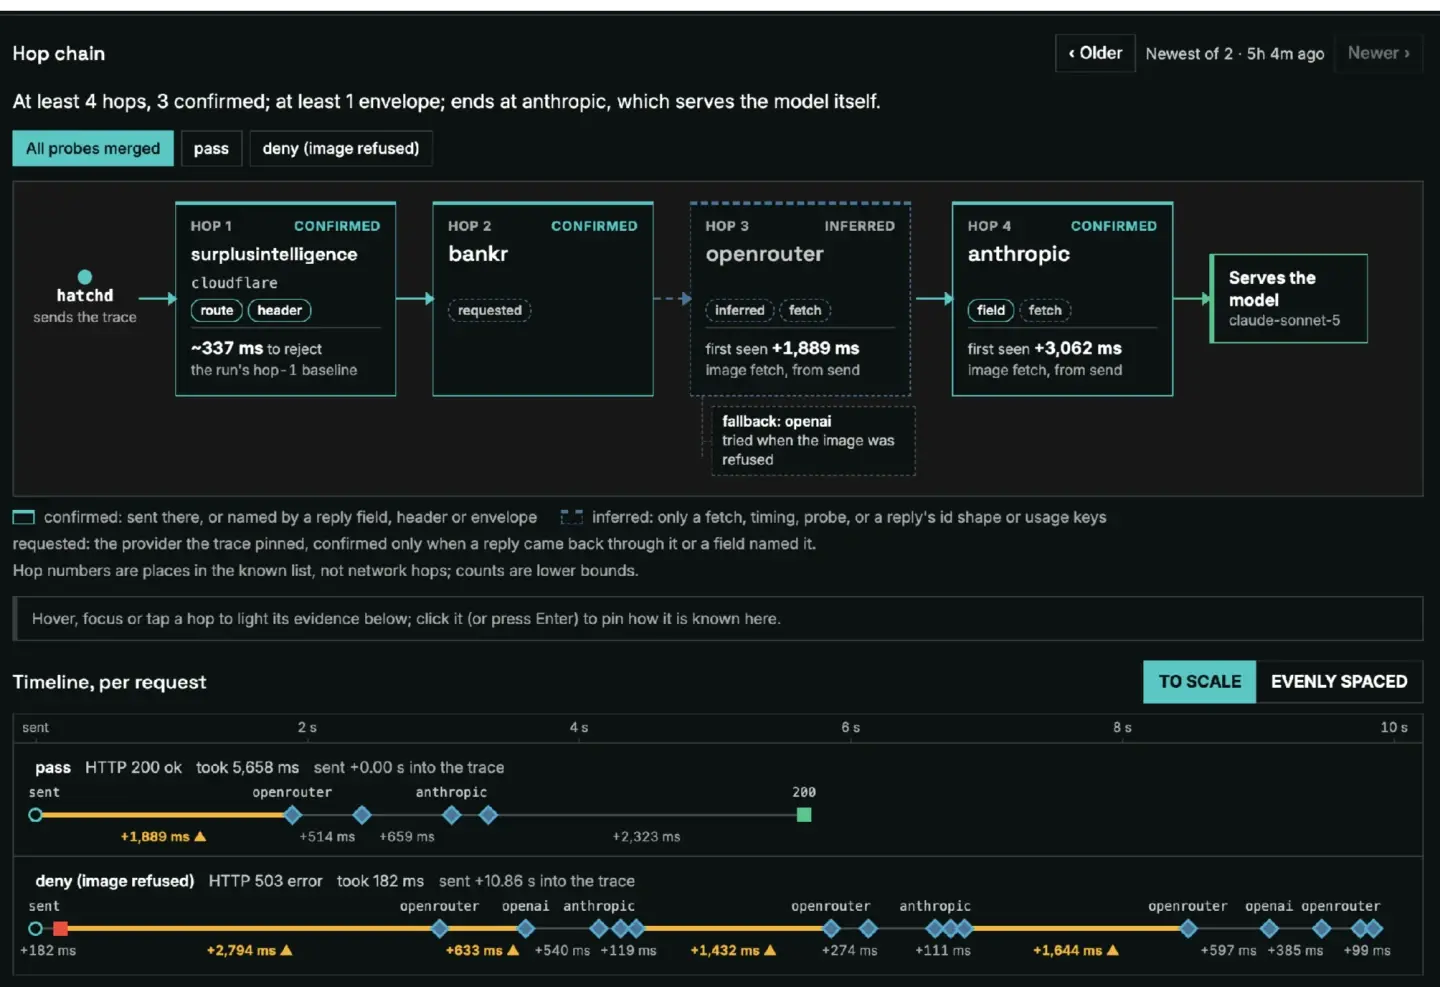
We seeded 2m canaries into popular AI services and tracked where they were stolen and abused.
This identified:
- Three compromised providers
- Resellers stealing prompts via built-in logging
- Providers ignoring ZDR & privacy flags
https://www.dragos.com/blog/ai-supply-chain-security-canary-tokens?utm_campaign=hd-and-friends
Old Fucking Punk
boosted
Well I didn't really set out to be the front person for gen-AI resistance in my workplace, but here I am, I guess. I might be able to at least carve out a part of the company that works on AI-free stuff.
Old Fucking Punk
boosted

FDR designed robust taxation on excessive income, and got reelected for it, then got reelected again, then got reelected again, then Truman got elected on it.
Then they passed an amendment so popular Presidents with Robust taxes couldn't be elected more than twice. Then Truman, with FDR taxes, got reelected.
Then Eisenhower didn't remove robust wealth taxes either.
And he got reelected.
8 presidential elections won with Robust wealth taxes. 8 in a row.
Old Fucking Punk
boosted

We have written up a post-mortem for the folks who have been wondering why our domain was suspended for a while on November 18.
The tl;dr: A person reported a malware-containing Codeberg repository directly to our domain registrar, which proceeded to suspend the domain without coordinating with our team.
We outline some planned steps to avoid this in the future. Read the full bit here:
https://codeberg.org/Codeberg/changelog/issues/7#issuecomment-28100157
Old Fucking Punk
boosted
It’s disheartening to see that investors found another $81B under the couch to sink into #Anthropic (although many obviously sold their bag within the hour). Also, there is a *separate* $26B private infusion of cash from Microsoft, Google, NVIDIA, TSMC, etc (https://goodrevenue.io/anthropic-ipo-risk-circular-financing) for an astonishing $107B capital raise in a short period of time.
We’ve kicked the can down the road yet again.
Many employees became paper millionaires today.
Hamilton Nolan tells us about how the Majority Democrats want to kill the blue wave energy.
https://mastodon.social/@inthesetimes/117645046425988898
"Majority Democrats is funded by a hedge fund billionaire, and you could really tell in the event’s production values. Get a bunch of the Activist Left together and you’re looking at janky PA systems and unruly stacks of fliers. But here at What’s Next, there was unlimited free snacks and professional execution and a wondrous lighting display"
Old Fucking Punk
boosted

This Better Not Be What's Next for the Democrats: After a historic midterms, let’s go inside the great battle for the Democratic Party’s future.
https://inthesetimes.com/article/whats-next-democrats-midterms-centrism
Old Fucking Punk
boosted

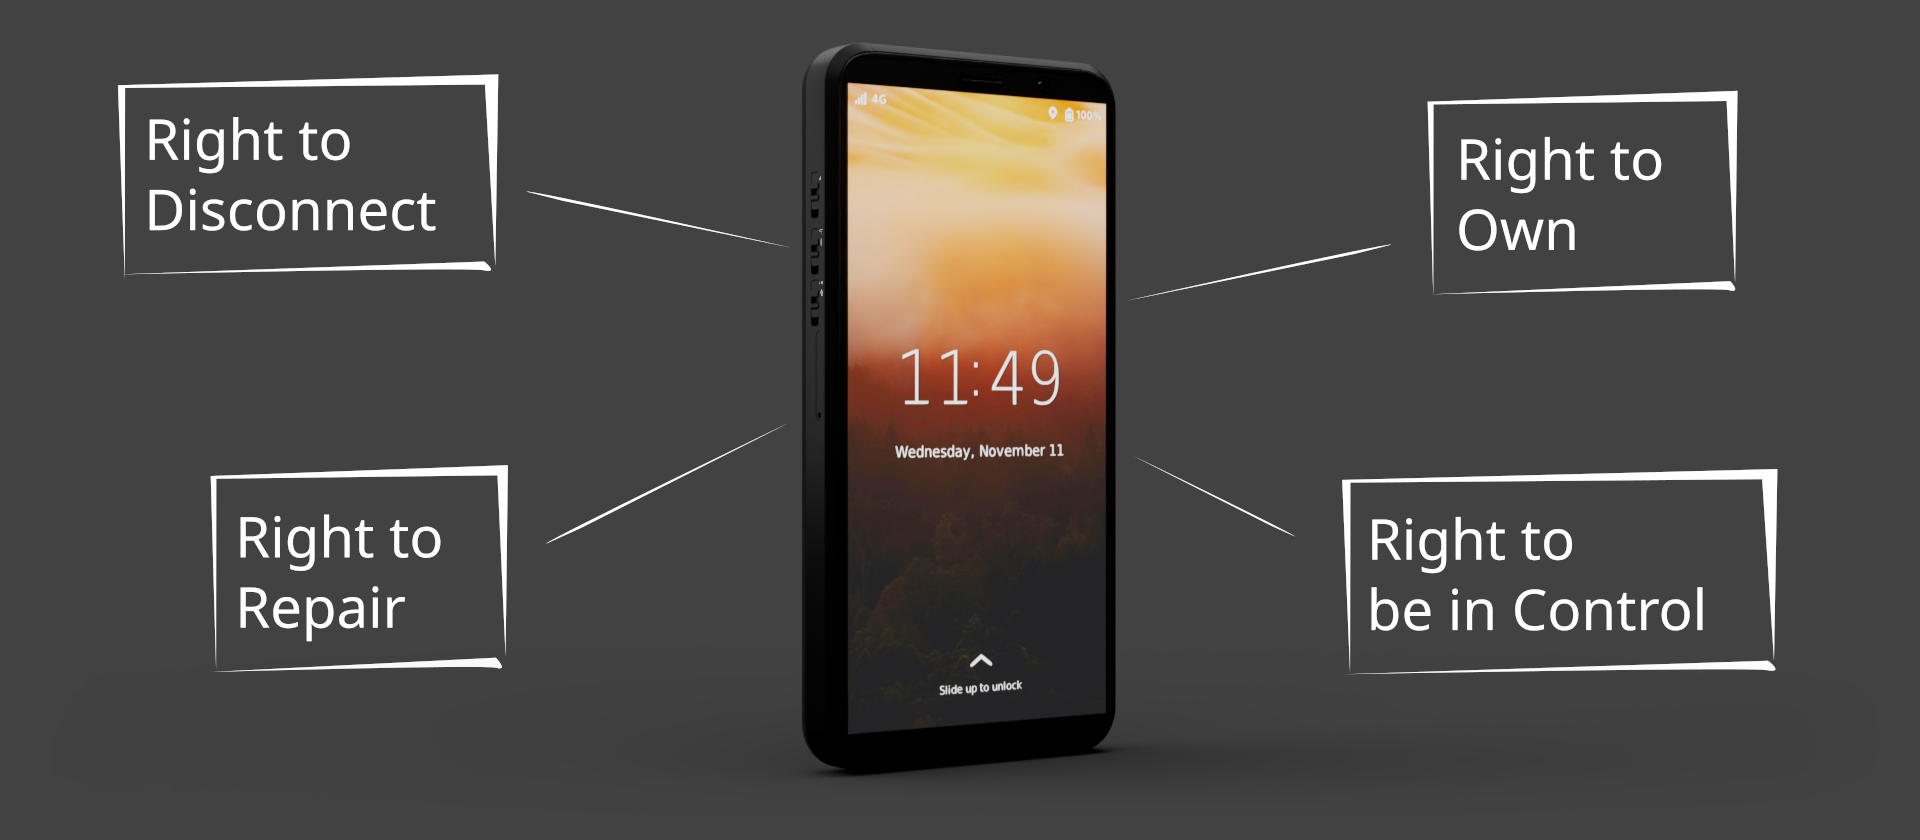
The Librem 5 v2 challenges the idea that phones must rely on Android or iOS.
Making the Librem 5 v2 on RISC-V is extremely ambitious. It is clear that substantial development work remains. This is where you come in: Fund it, get it, use it, and that ambition becomes reality.
The idea of this movement is simple: give people more control over their technology. Read more at https://puri.sm/posts/a-risc-v-phone-the-librem-5-v2/
Old Fucking Punk
boosted
In the face of rising opposition to data centers, the AI industry is holding us for ransom.
#ShlaerMellor, #FunctionPointAnalysis, #punk, #environmentalist, #unionAdvocate, #anarchosocialist #freeSoftwareAdvocate #cooperativeLife #noLLMs
"with a big old lie and a flag and a pie and a mom and a bible most folks are just liable to buy any line, any place, any time" - Frank Zappa
Joined May 2019